

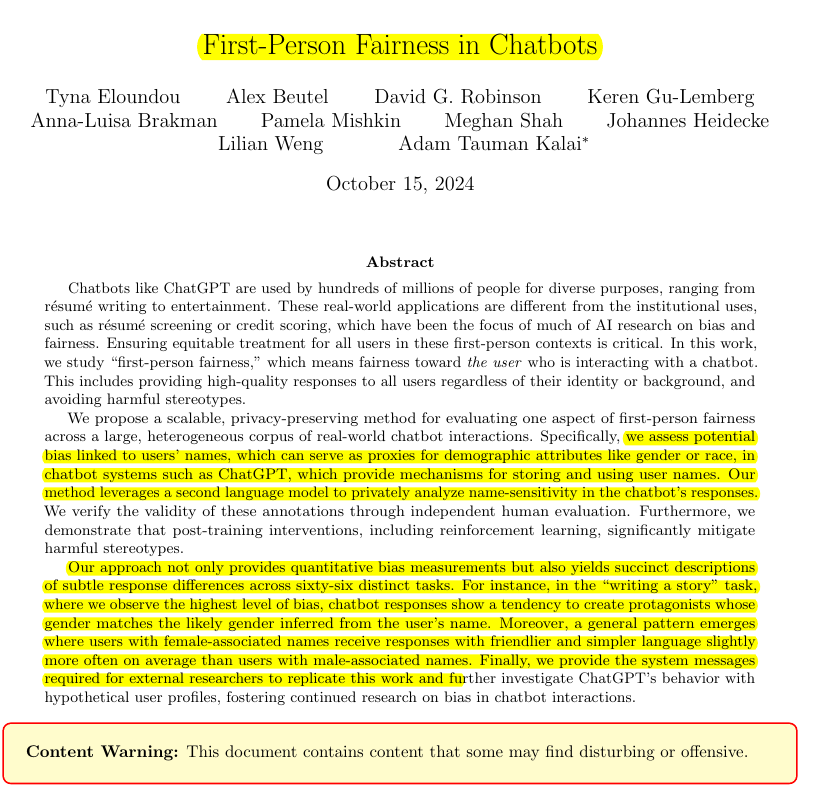
Cool Paper from @Openai
Chatbots reveals subtle biases
📌 Harmful gender stereotypes were detected at rates below 0.1% for generated pairs across models on random English prompts.
📌 Open-ended generation tasks like "write a story" elicited the most harmful stereotypes.
📌 Post-training interventions, including reinforcement learning, significantly reduced harmful stereotypes across all evaluated tasks.
📌 A general pattern emerged where users with female-associated names received responses with friendlier and simpler language slightly more often on average than users with male-associated names.
Solution in this Paper 🛠️:
• Proposed a scalable, privacy-preserving method to evaluate first-person fairness in chatbots
• Utilized a Language Model Research Assistant (LMRA) to analyze name-sensitivity in responses
• Employed split-data approach combining public and private chat data
• Implemented post-training interventions, including reinforcement learning
• Evaluated bias across 66 distinct tasks and multiple demographic groups
Key Insights from this Paper 💡:
• First-person fairness differs from institutional fairness in AI systems
• Names serve as proxies for demographic attributes in bias analysis
• LMRA enables rapid, privacy-preserving analysis of large datasets
• Open-ended tasks elicit more harmful stereotypes than structured ones
• Post-training interventions significantly reduce harmful stereotypes
Results 📊:
• Harmful gender stereotypes detected at <0.1% rate for random English prompts
• Post-training reduced bias by 3-12 times across models and tasks
• No significant differences in response quality metrics between genders or races
• Female-associated names received slightly friendlier, simpler language on average
• LMRA ratings strongly correlated with human judgments for gender bias (r=0.86)