

Read time: 11 min
📚 Browse past editions here.
( I publish this newletter daily. Noise-free, actionable, applied-AI developments only).
⚡In today’s Edition (14-July-2025):
🚨 Mark Zuckerberg says Meta is building a 5GW AI data center
📡 xAI will spin Grok into hundreds of task-focused agents that talk to each other.
🛠️ Cognition AI is taking Remaining Windsurf team and tech, days after Google bought its founders for $2.4B
🗞️ Byte-Size Briefs:
Pentagon picked Google, OpenAI, xAI, and Anthropic for new defense deals. Each agreement carries a spending limit of $200 million.
🧑🎓 Deep Dive: Reinforcement Learning Needs More Than 1 Number, says Andrej Karpathy
🚨 Mark Zuckerberg says Meta is building a 5GW AI data center
Mark Zuckerberg announced Meta will spend hundreds of billions building AI data centers that each pull gigawatt-scale power, chasing models that out-think humans. As part of this, he also earlier stated that Meta will also be investing US$65bn in AI in 2025.
He confirms that they are building multiple GW clusters. 1000MW Prometheus will come online in 2026 and Hyperion will be built in phases and be able to scale to 5000MW+. For context, the largest H100/H200 clusters operational today is only 150-200MW.
Prometheus, its planned AI super-compute campus, goes live in 2026 and Hyperion (the bolder sequel to Prometheus) later ramps to 5 GW, all paid for by Meta's own capital. Zuckerberg said Hyperion’s footprint will be large enough to cover most of Manhattan. Prometheus will be online in 2026, making it one of the first tech companies to control an AI data center of this size.
Meta folded every AI project into Superintelligence Labs after Llama 4 stalled. Bigger models need far more compute, so the plan pivots from “add servers” to “build mini-power plants”.
A single 1 GW cluster can host tens of thousands of cutting-edge GPUs, matching the electricity draw of a mid-size nuclear unit.
Designing that much power and liquid cooling under one roof means custom grid ties, on-site substations, and new waste-heat recovery tricks, not just racks and cables.
Capital spending for 2025 already sits at $64-72 B and rises from there.
Mark Zuckerberg argues the ad business throws off enough cash to fund the gamble. Leadership poached top builders like Alexandr Wang and Nat Friedman, betting their know-how plus vast compute equals a lead over OpenAI and Google.
If Prometheus hits schedule, Meta’s network latency drops, training cycles shrink, and fresh revenue streams—Meta AI chat, video ads that write themselves, smarter glasses—arrive faster. Investors still wonder when those billions loop back, especially with electricity prices and chip supply both volatile.
A single gigawatt cluster marks a shift: compute is now limited by grid wires, not silicon.
And last week I discussed whey Meta is getting super serious, because ChatGPT Is Turning Into The Busiest Hangout Online, And That Scares Meta
📡 xAI will spin Grok into hundreds of task-focused agents that talk to each other.

Elon Musk said, that they are “creating a multi-agent AI software company xAI, where Grok will spawn hundreds of specialized coding and image/video generation/understanding agents all working together and then emulates humans interacting with the software in virtual machines until the result is excellent.”
With $2 B in fresh SpaceX backing and a valuation reported at $113 B, xAI now has the cash to chase OpenAI and Google on the agent frontier.
AI agent architecture that can simulate real humans in ways far more complex than traditional approaches. Stanford HAI recently showed that agent swarms can recreate answers from 1,000 real survey participants, hinting at realistic human-in-the-loop testing in silico.
Agent teams split long coding tasks: one drafts functions, another writes tests, a third trims dependencies. Images and video follow the same pattern—specialist agents handle layout, color grading, and captioning, then merge outputs.
And Musk wants the agents to run whole apps inside headless virtual machines, clicking buttons and writing files the same way a person would
The timing is no accident. OpenAI, Google, and Anthropic all previewed agent toolkits this quarter, and Cognition’s Devin pitch full-stack AI workers.
Goldman Sachs is piloting Cognition's Devin, an autonomous coding agent, and expects to deploy hundreds or even thousands of these bots alongside its 10,000 human software developers, letting the machines write, test, and ship routine code inside secure sandboxes.
We are on a fast route to a working AI “factory floor”.
Common Technical hurdles that need to be overcome
Latency grows when 100+ agents wait on each other.
GPU memory balloons, even with parameter-sharing tricks.
Coordination failures can snowball; an agent might pass bad context that derails the group. arXiv surveys list environment design, memory, and evaluation as open pain points.
Grok also adds a ridiculous anime companion with ‘NSFW’ mode
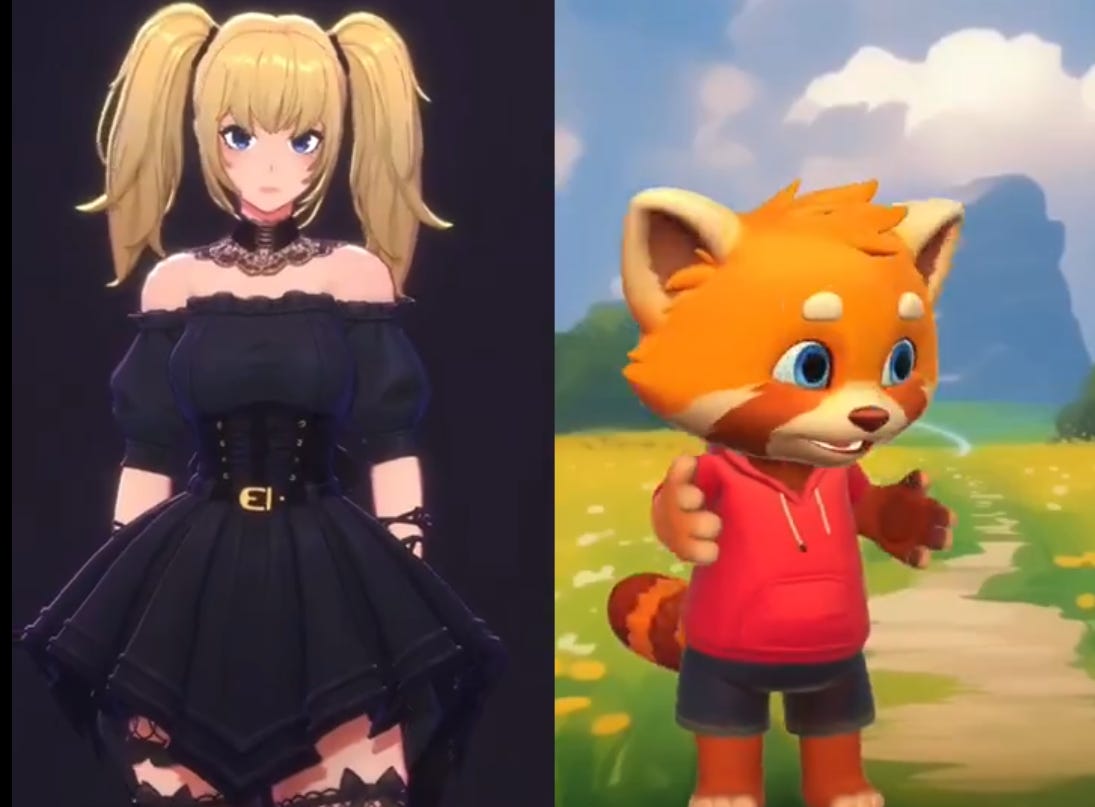
SuperGrok just added animated AI companions Ani and Rudy; Ani even hides an optional NSFW outfit. The avatars live inside Grok’s voice chat and, for now, users flip a setting to meet them, though xAI promises a simpler switch soon. You need to Update your app to try out Grok companions!
These companions are not mere stickers. Grok streams its usual large-language-model replies through a real-time animation pipeline, so Ani tilts her head or flashes a shy wink while the text comes back. The same speech-to-text loop that already powers Grok’s voice mode now layers 3D rigging, lip-sync, and emotion tags on top, then pushes a compact animation stream to the app.
That keeps bandwidth low while the GPUs crunch the language response in xAI’s cloud. A similar tag drives the NSFW flag, swapping Ani’s default costume for lingerie once the user’s relationship level or toggle allows it; Rudy’s “Bad Rudy” mood works the same way.
Security engineers slipped the avatars behind the same guardrails that filter Grok’s text. xAI allows adventurous users unlock more daring modes because the images themselves stay client-side, limiting server liability.
A third avatar, Chad, sits in the build and hints at constant content drops that mimic game seasons. At $30 per month for SuperGrok, xAI is betting that playful skins plus voice chat will keep subscribers around longer than plain text.
How to enable Companions on SuperGrok?
01. Click the two bars on the top left.
02. Select the gear icon at the bottom right.
03. Enable the Companions slider.
🛠️ Cognition AI is taking Remaining Windsurf team and tech, days after Google bought its founders for $2.4B
Cognition AI is taking Windsurf’s code, brand, and $82M revenue days after Google bought its founders for $2.4B, slotting the prize under a $4B valuation.
No acquisition amount was disclosed publicly, nor were specific terms of the deal (both are private startups). The acquisition gives Cognition access to Windsurf’s core product, brand, and remaining team — but not its original CEO or co-founders, several of whom have now joined Google
So basically, Google took the captains, Cognition got the ship. Google sidestepped a full purchase by licensing the tech and hiring the chiefs, a play that avoids antitrust noise yet strips the startup of leadership.
Google gains Windsurf’s trained weights plus the brains that built them. In code generation, those weights decide how well an LLM predicts the next line of source. Cursor, Anthropic, and others already fight for this space. So moving them means Windsurf’s best ideas now can fuel Google’s stack, crushing any advantage the stand-alone remnant holds.
Cognition grabs the rest, promises instant vesting for every engineer, and will feed Windsurf’s data into Devin, its automated coder, hoping the extra examples cut hallucinations and widen language support.
Wang also stated in the announcement video: “And of course, we’re friends with Anthropic again,” a reference to Windsurf’s prior falling out with Anthropic, that resulted in Anthropic Claude models being pulled from the list of options that developers could rely on to power their Windsurf AI coding agents and processes.
Cognition’s future strategic direction
The Cognition-Windsurf combo now goes head-to-head with GitHub Copilot, Replit, Cursor, Google’s Gemini, and Visual Studio Code’s agent mode. Earlier, Devin drew attention by fixing GitHub tickets and finishing coding jobs on its own. Blending that skill with Windsurf’s Previews, Reviews, and Enterprise flows could trim silos and crank up automation beyond what rivals manage.
🗞️ Byte-Size Briefs
Pentagon picked Google, OpenAI, xAI, and Anthropic for new defense deals. Each agreement carries a spending limit of $200 million.
On this, Anthropic said in its official announement, that Engineers will fine-tune Claude on classified data, plug it into secure chat and data-fusion dashboards, and stress-test it against spoofing or hallucination tricks. Anthropic already runs Claude Gov inside Palantir’s classified networks and at Lawrence Livermore Lab, where researchers parse nuclear materials data faster than manual review. Those wins gave DoD confidence that the model can handle real-world security stakes.
xAI also said, Grok for Government makes xAI’s frontier models available; it holds a new DoD contract and sits on the GSA schedule, so any federal agency can buy.
So The Pentagon is hedging its bets. Google, OpenAI, and Musk’s xAI each won a similar $200 M ceiling, keeping competition tight and reducing vendor lock-in.
🧑🎓 Deep Dive: Reinforcement Learning Needs More Than 1 Number, says Andrej Karpathy
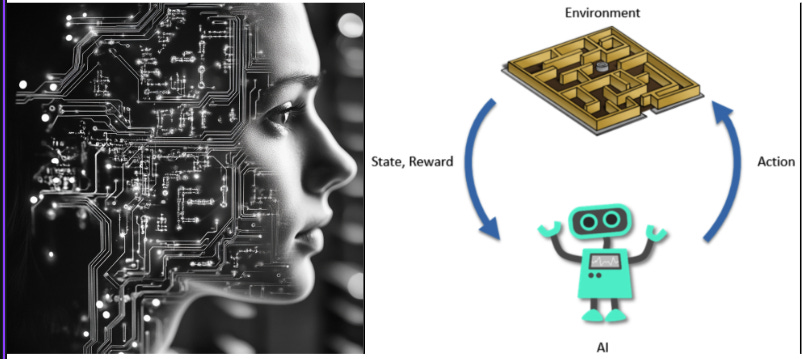
Andrej Karpathy write s along post on Twitter and he thinks reinforcement learning (RL) still brings solid near-term wins, yet he sees a ceiling because today’s setups squeeze 1 reward number out of a whole task.
What’s this “1 reward number out of a whole task”?
Reinforcement learning, or RL, treats an AI agent like a gamer who only sees the final score once the game ends. The agent tries a bunch of moves, waits, and then receives 1 number that says “good” or “bad”. For short arcade-style tasks that single score works fine. For long jobs that stretch over many steps, it hides most of the useful details.
Andrej Karpathy points out that this single-score habit still brings quick wins right now, yet it creates a ceiling. Long tasks such as writing code, answering multi-part questions, or planning a robot routine need richer feedback. If the agent only hears 1 number after all those steps, it struggles to understand which decision helped and which hurt.
Karpathy’s fix is simple. After the agent finishes its run, let it read its own work, write down what worked, note the mistakes, and store those lessons for next time. People do this when we study: we spot the error, jot a short reminder like “count letters one by one”, and carry that note into the next attempt.
Real research groups already test this idea. One project called Satori adds a review loop that lets a 7B-parameter model reflect on each reasoning path before updating its policy, and that smaller model now tops math benchmarks that used to need larger systems.
📚 Lessons, review, reflect
Karpathy argues that people learn by pulling many insights out of each attempt, writing them down, then distilling them into intuition later. Research is moving that way. Satori trains a 7B model with a Chain-of-Action-Thought loop that includes self-reflection before updating policy weights, and the authors report state-of-the-art math scores after reinforcement fine-tuning arXiv. Nvidia’s Eureka uses GPT-4 to propose and refine reward code through iterative critique, beating expert-designed rewards on 83% of 29 robotics tasks eureka-research.github.io. These projects show that extra textual feedback, not just the scalar, makes RL far more data-efficient.
💾 Memory as a quick patch
Karpathy mentions how Claude fixes its letter-count bug by adding a prompt line telling itself to list letters one by one. That pattern mirrors OpenAI’s rolling-out memory: ChatGPT now stores user-specific facts and injects them into new chats.
Claude’s internal prompt literally instructs it to separate letters by commas before counting, solving the famous “how many R’s in strawberry” failure.
Nvidia’s Eureka toolkit goes a different route, asking GPT-4 to write and revise reward code, then beating expert-designed rewards on 83% of 29 robotics tasks. Even mainstream products follow the pattern: ChatGPT’s memory feature stores user facts or special instructions so the model stops repeating old mistakes.
So start with the classic RL loop—try actions, get 1 score—but bolt on a written self-review that captures many small signals. Feed those notes back in, and the agent learns faster and pushes past the ceiling that comes from relying on a single number.
🔬 What other research says
RL with AI feedback scales better than human labeling and keeps parity on helpfulness and harmlessness metrics (arXiv).
Chain-of-thought verification combined with RL improves alignment scores in Anthropic’s tests (arXiv).
Autoregressive search plus reflection, as in Satori, outperforms pure supervised fine-tuning on math benchmarks (arXiv).
All of these studies suggest that richer intermediate signals—self-critique, memory strings, code rewards—push models past the plateau Karpathy worries about.
🤔 My take
RL is not going away, but it starts to shine only when paired with explicit feedback channels that tell the model what went well, what failed, and how to change next time. Storing those bits either in a reward model, a memory bank, or a prompt “lesson” shrinks the sample complexity and closes obvious gaps like counting letters or following multi-step instructions. Future gains will likely come from stitching these pieces together: an RL core, a fast verifier that drops detailed comments, and a memory module that remembers the comments so the system stops repeating old mistakes.
That’s a wrap for today, see you all tomorrow.