

https://arxiv.org/abs/2501.14677
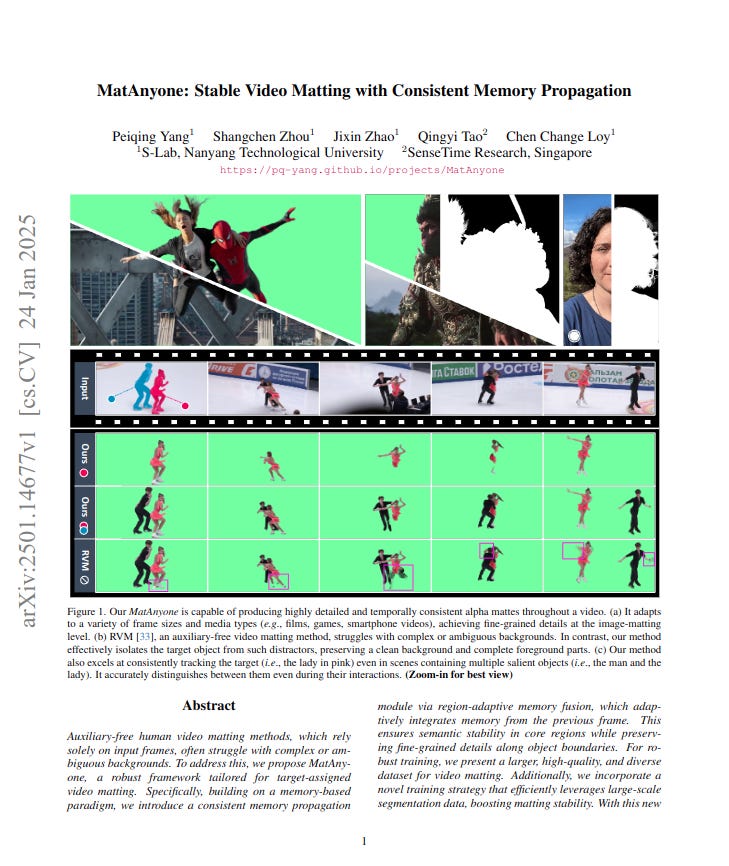
Auxiliary-free video matting methods often fail in complex backgrounds and lack temporal consistency. This paper addresses video matting for a pre-assigned target object in the first frame to achieve stable and interactive matting.
This paper introduces MatAnyone, a memory-based framework. It uses consistent memory propagation and core-area supervision to deliver robust and detailed video matting.
-----
📌 MatAnyone's consistent memory propagation module tackles video matting's temporal instability effectively. Region-adaptive fusion smartly balances current frame details and past memory for stable, high-quality mattes.
📌 Core-area supervision innovatively uses segmentation data to directly train the matting head. This strategy overcomes video matting data scarcity, boosting semantic stability and real-world generalization.
📌 Scaled DDC loss refines boundary regions, producing natural edges without ground truth alpha mattes for segmentation data. This loss function is crucial for detail preservation and matting quality.
----------
Methods Explored in this Paper 🔧:
→ MatAnyone uses a memory-based framework. It is inspired by semi-supervised Video Object Segmentation.
→ It introduces a Consistent Memory Propagation module. This module uses Region-Adaptive Memory Fusion.
→ Region-Adaptive Memory Fusion adaptively integrates memory from the previous frame. It estimates alpha value changes to differentiate between core and boundary regions.
→ "Large-change" boundary regions rely on current frame information from memory. "Small-change" core regions retain memory from the previous frame. This stabilizes memory propagation.
→ The framework includes an Alpha Memory Bank to store alpha mattes. This enhances boundary region stability and reduces flickering.
→ A Core-area Supervision training strategy is proposed. It directly supervises the matting head using real segmentation data.
→ A Scaled DDC loss is introduced for boundary regions during core-area supervision. This loss makes edges resemble matting rather than segmentation.
-----
Key Insights 💡:
→ Consistent Memory Propagation enhances temporal stability and detail quality in video matting.
→ Region-Adaptive Memory Fusion stabilizes core regions and refines boundary details.
→ Core-area Supervision with segmentation data improves semantic stability and generalization.
→ Scaled DDC loss in core-area supervision yields more natural matting edges compared to original DDC loss.
→ A new training dataset VM800, improves robustness due to its larger size, higher quality and diversity.
-----
Results 📊:
→ MatAnyone achieves a MAD of 0.18, MSE of 0.11, and dtSSD of 0.95 on real-world benchmarks. This outperforms existing auxiliary-free and mask-guided methods.
→ On the VideoMatte benchmark at 1920 × 1080 resolution, MatAnyone achieves a MAD of 4.27 and dtSSD of 1.24, the best among compared methods.
→ On the YoutubeMatte benchmark at 1920 × 1080 resolution, MatAnyone achieves a MAD of 2.05 and MSE of 0.76, again the best performances.