

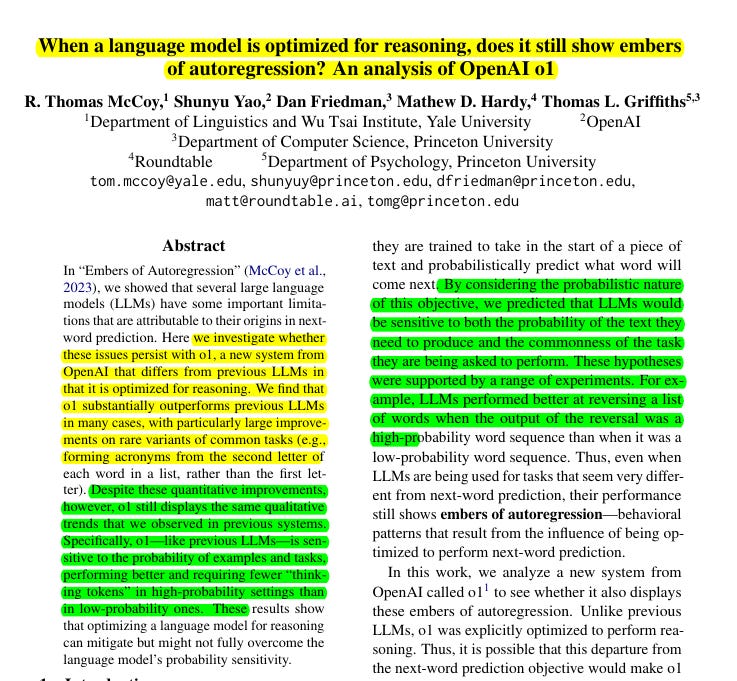
Despite reasoning upgrades, OpenAI's o1-preview's brain still thinks in probabilities, just like earlier language models.
Original Problem 🔍:
LLMs trained on next-word prediction show limitations when used for reasoning tasks. Previous research identified "embers of autoregression" - behavioral patterns resulting from this training objective.
Solution in this Paper 🧠:
• Analyzes OpenAI's o1 model, optimized for reasoning using reinforcement learning
• Evaluates o1 on tasks like decoding ciphers, Pig Latin, article swapping, and word list reversal
• Compares o1's performance to other LLMs on common and rare task variants
• Examines o1's token usage as an additional metric of task difficulty
Key Insights from this Paper 💡:
• o1 outperforms previous LLMs, especially on rare task variants
• Despite optimization for reasoning, o1 still shows sensitivity to output probability and task frequency
• Token usage reveals difficulty differences even when accuracy is similar
• Probability sensitivity may arise from text generation process and chain-of-thought development
Results 📊:
• o1 accuracy on shift ciphers: 47% (low-probability) to 92% (high-probability)
• o1 shows less task frequency sensitivity than other LLMs
• o1 uses more tokens for low-probability examples and rare task variants
• o1 achieves 100% accuracy on common acronym task, 99.9% on rare variant
🧮 The findings related to o1's sensitivity to task frequency
o1 showed less sensitivity to task frequency compared to other LLMs, often performing similarly on common and rare task variants. However, when faced with more challenging versions of tasks, o1 did display some sensitivity to task frequency, performing better on common variants.